Showing posts with label Coding. Show all posts
Ok, so in reality this release happened a while ago... but it has taken me until now to actually write about it.
This work has been going on in the background of my life for a while — true, the birth of my daughter definitely pushed what was already background beyond whatever layer you might imagine lies behind that. But considering Pebbl has been in development since 2007, it is probably used to coming second fiddle to everything else.
Prior to this recent release, I had been playing around with Unity (something which I completely failed to mention here, and I still won't, because the work — not the knowledge or the technology — is now obsolete).
You can see those experiments (along with other previous examples) by clicking one of the images below. Be warned you will need the Unity Player installed for some of them.



Part of life as a developer is to be constantly checking and re-checking what is available to help do your job. Over the nine years of Pebbl works, I haven't just been naively re-inventing a wheel with my bespoke code. I have constantly been on the look out for decent Game Dev libraries. Those that will help me speed up my work, whilst at the same time give me the control that I need.
This research has spanned a number of solutions: EaselJS, PaperJs, Box2D, Unity, Early Phaser, D3, Three, and then smaller subsets like TweenJS, Spine (for animation), and PolyK (for polygon handling). If you combine the above with all my work on ALWTM, the effort spans further into other technologies like Flash, Silverlight, C# and more.
Unfortunately, for all my attempts, I couldn't find anything fully satisfactory. Hence the reason for trying to building my own libraries with very small amounts of free time. Certain libraries would start off promising, only to fall down at some pivotal point later on. Usually this would either be in terms of performance, or a particular missing feature. That is at least until I started using Pixi.js, and the more recent version of Phaser. Both have given me the ability to happily put together the following:

True, I must be quite demanding customer when it comes to Game Dev libraries. Considering there are a lot of Games and "games" already out there, that have been powered by the technologies I have already mentioned. But there are a number of abilities that I want my online worlds to have, that have ruled out a lot of what is on offer (at least not without some serious extension of existing code).
Polygons, where for art thou Polygons?
One key issue is the ability to hit test against polygon shapes. I flirted (as mentioned above) with complex physics engines for a while. Most give you this ability (at least for convex polygons) out of the box. The problem is, whilst you may gain a lot from a physics engine like Box2D — it simplifies very complicated interactions — it actually complicates all the other parts of a game that would usually be easy to code. The likes of working with platforms consistently, or just trying to get objects to sit still, becomes a real headache — especially if you insist on slopes.
The curving of a slope
This has been the part that has made nearly all my personal projects difficult. I could obviously just concede and produce another platformer with a tile map; but where would the fun be in that? Both ALWTM and Pebbl require slopes — Pebbl is very annoying in that it requires curved platforms... and I have yet to come across a Game Dev library that helps properly with this (without using a physics engine). I attempted to use Phaser's Ninja Physics, but it wasn't flexible enough — but to be honest, what I'm requesting is a tall order.
Latest version
Pebbl v0.3 still uses Phaser (powered underneath in part by Pixi) but I've added in my own collision handler called imagination.js:
http://pebbl.co.uk/v0.3/scripts/imagination.js
I say my own, but to be honest the hard work so far has been done by the brilliant PolyK library — without which I think I would have given up.
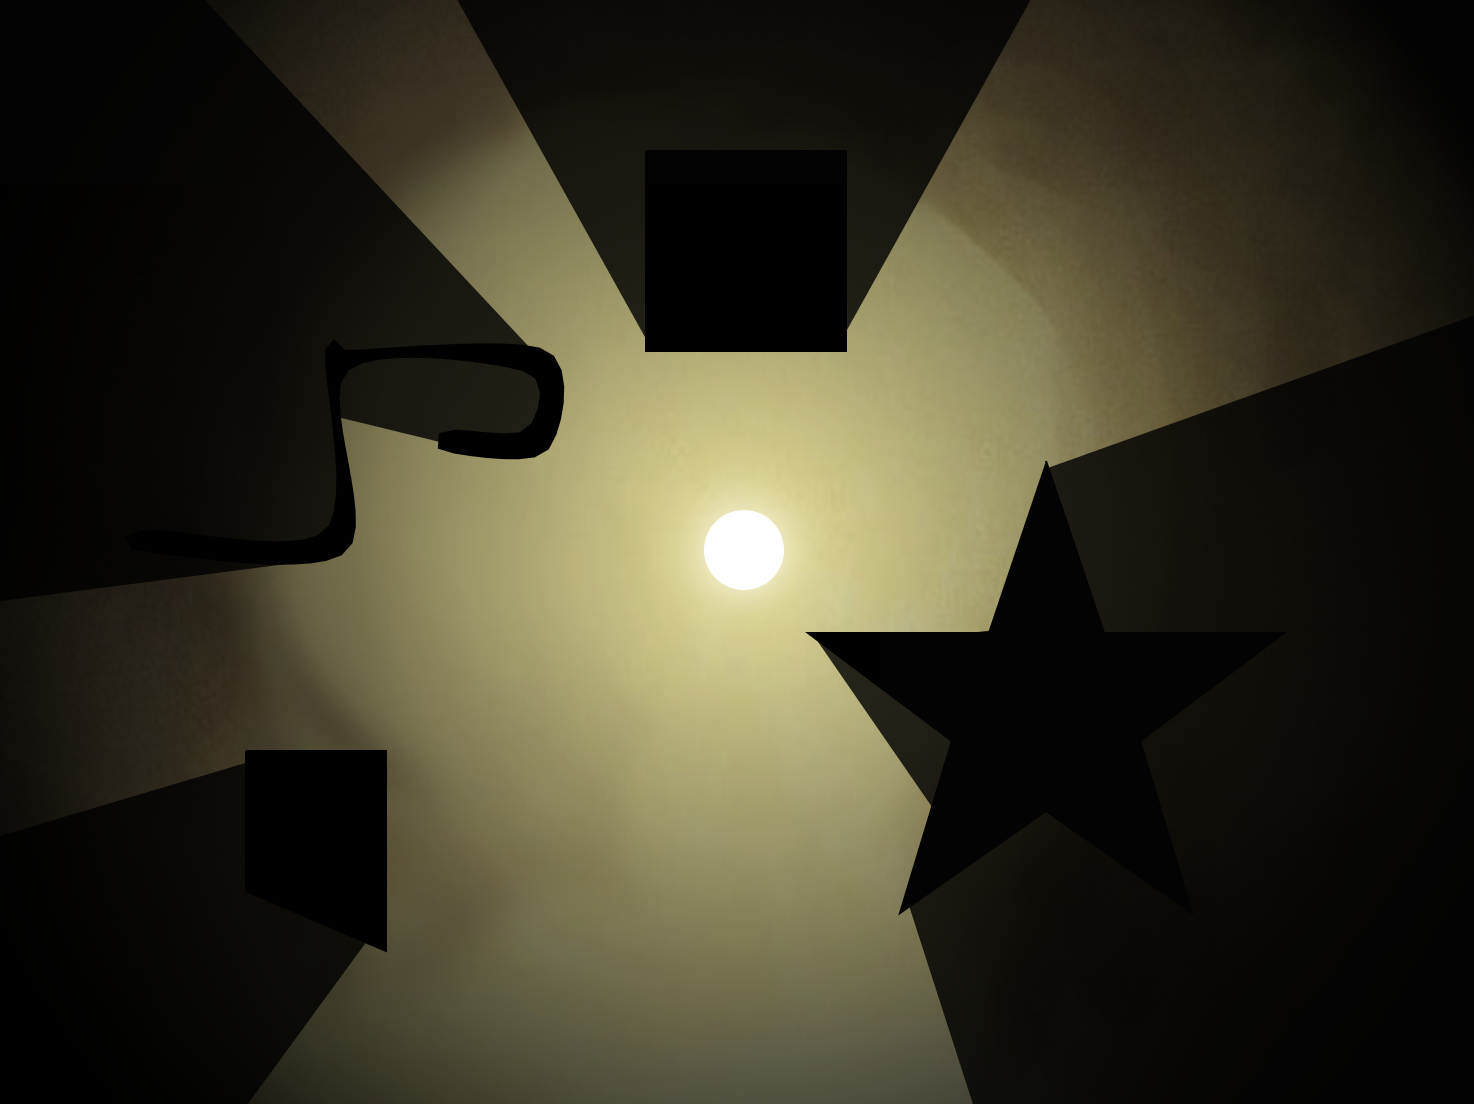
For Pebbl, the PolyK lib allows me to raycast out from an entities position, and detect if there was a collision against quite complicated shapes. The system is still very buggy — as you will see in the demo. Especially if you attempt to walk underneath the plant. But this method is much easier to build a game around than using a physics engine; and I will iron out the kinks over time.
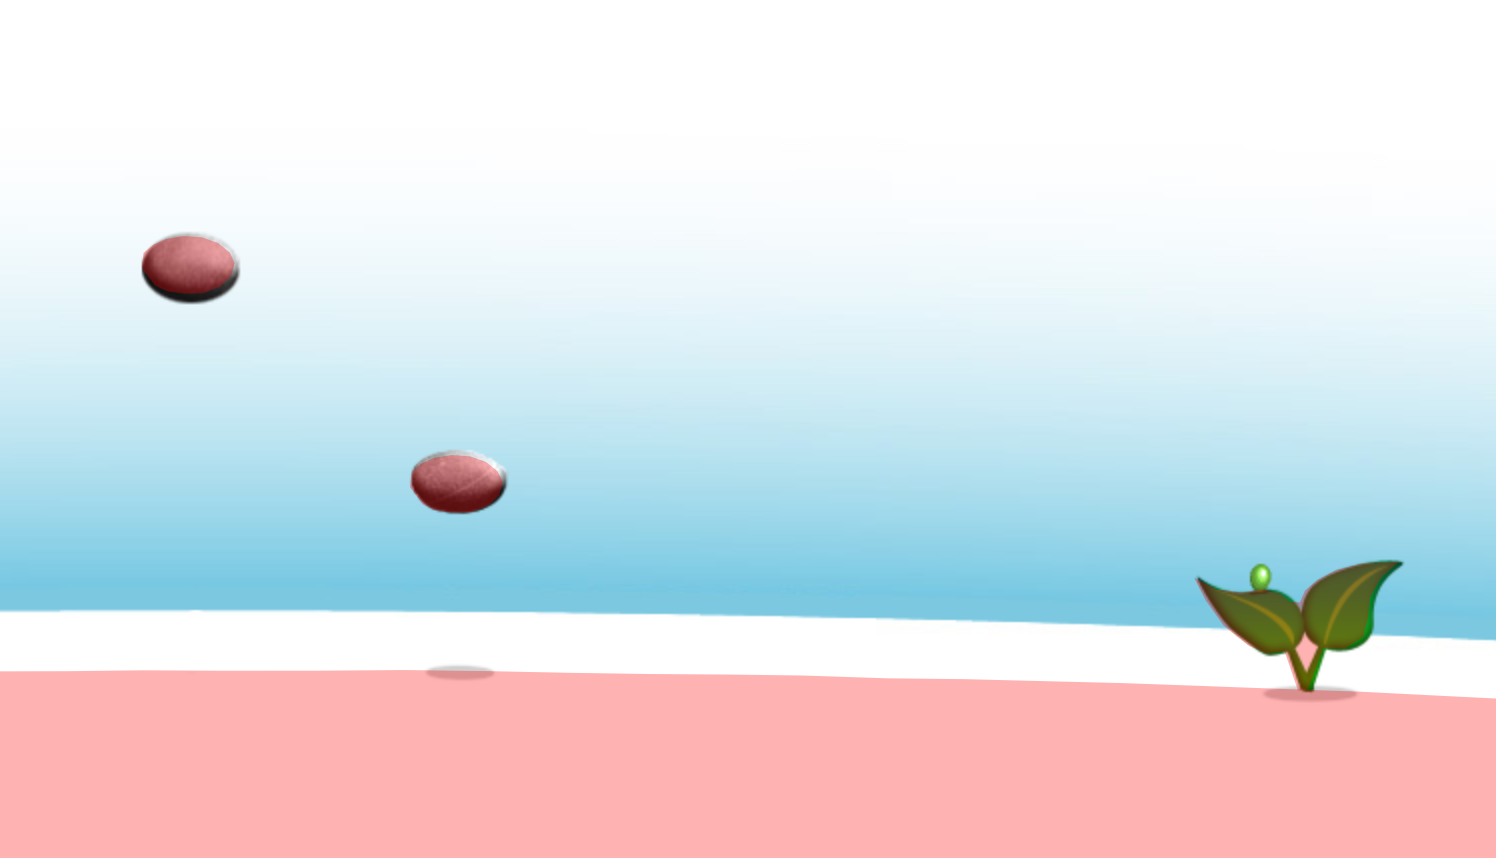
This system allows me to add polygon hit areas to static (or programmed motion) entities. I don't think I'll extend the work to dynamic motion entities just yet (not until I can get static to work properly). This at least will cover all the elements I actually need to support polygons... for now.
- Leave your comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit

Just a quick post to say I've just turned 32 (Good old binary offsets) and, not only that but I've also released a new web publish of my first "Long Way Till Morning" Unity Scene... Oh Yeah! It now comes with added Particle Systems to handle weather effects, plus I've improved the terrain generation using a very nice unity plugin / import called "Ferr 2D Terrain". This should mean I can start chucking together new scenes in a much more expedient manner... Scenes which will all support damn nice lighting, particles, multiple cameras and physics all from the get-go.
Coming up next:
- Character Animation Control, both Pixel KeyFrames and Spines.
- LostBeach Scene.
- Multiple Terrain interaction, Annabell will be able to choose which terrain she can travel on, allowing for less linear gameplay.
- Submaps, allowing Annabell to travel into smaller regions like her House or the Church (both found, but not yet implemented in the demo).
Oh and P.S. Watch this space for a Unity update with regards to Pebbl!
For now though, I'm off to bed.
- Leave your comment • Category: C Sharp, Coding, Game Dev, JavaScript, Particle Systems, Shaders, Textures, UnityScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
Most definitely A Long Way Till Morning
I can't quite believe that after another period of indeterminacy I've managed to cobble together yet another step forward on my path to creating a worthy online/offline platform adventure game... Obviously over all this time I've been developing game assets, which takes a lot of energy, but I haven't made much progress in the way of a Game Engine; beyond what I've tinkered with in the HTML5 space.
That's recently changed all thanks to Unity and their latest 2D release.
Unity (the Game development tool, not the Microsoft "extensible dependency injection container") is something I've had my eye on ever since it first started. It popped up at the time where I wasn't sure if I was going to invest time into building my own 2D platform engine in Flash, JavaScript or perhaps something else... I stumbled across their homepage and was rather impressed with the types of games they had running from within a browser environment.
At the time however it was much more geared towards 3D, so much so that after downloading the dev environment I found myself getting lost in the likes of Blender, 3D meshes, Shaders (if you think usual programming languages are gobbledygook, try Shaders) and fighting with 3D Cameras and Lights to appear 2D, whilst keeping pixel definition. So after getting frustrated I left my .unity project files to gather dust, but I signed up to the Unity mailing list and kept an eye on new releases.
Unity 4.3
Nothing much happened in the way to interest me, with my specific requirements, for a good number of years.. that is, until they released Unity 4.3 with added 2D support. To cut a long story short I downloaded the upgraded version and within a month of weekends I've imported my assets using a mixture of Spine and 2DToolKit, and have got a rough parallax demo up and running with simulated physics out of the box:
Unity Demo (A = left, D = right, Space = jump).
I still have a lot to tweak, and getting the camera to stop scaling with different window sizes is my first priority, but the main thing that Unity has help me with is to make easy all the things I would have found very time consuming and tricky to balance cross-device — like physics, lighting and layer effects... the downside being that it has quite a steep learning curve and all the things I would have found easy in either Flash or HTML5 are now the difficult things — Text handling, GUI adornments, asset loading and management, pixel perfection and pixel collisions... But hey, if it was too simple I probably wouldn't enjoy doing this in the first place.
Just read through yet another article stating how there needs to be more women in tech, and putting forward the notion that it's all because there isn't anything specific or special in place for women.
I can tell you the two main reason why there were less women into computers/science whilst I was at school. One, because it wasn't seen as the 'cool thing to do' and two, because young girls generally are extremely bitchy between themselves and belittle anyone that seems to be on a different path from the zeitgeist of magazines, trends and popular society. Young boys are often the same, but more in the direction of vying to be the best, and poke fun at those that are weaker.
To be honest there were hardly any people (notice no gender there) that were into computers, and I mean really into them, in terms of actually seeing and understanding the power and beauty of structure and code. In fact most people really didn't have the time of day, and those that were good at programming, or science, or maths were shunned and bullied as geeks. I knew a few girls who were geeks but they were shunned just the same as the guys; the downside being that they were probably shunned by their fellow girls more than the guys.
So whereas the BBC article below does state that there is a "worryingly" small percentage of women in the tech industry, the article doesn't put it in perspective and state that actually, there aren't many people in this country in that industry (hence the reason for the recent drives towards coding)... and if the teaching I received is anything to go by — when computers were far easier to hack and understand — I am not surprised things have not improved.
What I'm trying to get at is there shouldn't be any special implementations for Women, there should just be a better drive towards the fun side of programming (which seems to be happening at least in some places); to show people what you can really achieve and how flexible your career can be. It should not just be based on 'hey, you can make lots of money in the latest gold rush' i.e. Apps (my main reason for disliking cheesy companies like Treehouse), or 'hey look, so many open source coders have done the work for you so you can just bolt third-party code together and job done!' which seems to be the extent of many newbie coders abilities.
100 Women: Why tech needs a makeover to attract girls
TBH. Isn't that BBC title rather sexist? Or does my definition of sexism require a `brew update`?
Disclaimer alert!
Before I get lynched, a little disclaimer. I am not stating that Women coding in the current work place do not have a harder time than their Male equivalents; I know of a number of Women who do hit problems that guys would not. This is mainly due to old-guard idiotism, unchallenged assumptions, or foolish macho behaviour. Sometimes it can also be down to the Women in question being more sensitive to a situation and cautious before making a move, which can be the difference between having an idea backed or a promotion given... basically there are definitely problems. My belief is the only solution is to get more people happy and confident with coding. What you most definitely should not being doing is involving positive discrimination.
Was just checking back over a few old sites that I worked on and realised that some of the easter eggs I built in were still there and working — considering I know the guys behind these site pretty well, and it's been a few years (try closer to 7), I don't think they'll mind if I at least point one out.
I'm of the opinion that sites should have more fun / hidden elements baked-in, rather than the increasingly impersonal, out-of-the-box and off-the-shelf sites that you see everywhere today. It's those kinds of playful elements that give a human touch and memory to the otherwise transient complexity that forms the web.

To find the above Flash map you just need to visit http://www.airportguides.co.uk. Checking the map you'll see that there are two thin lines that cross at one point, triple click where the lines cross (you should get a pointer cursor) and then you should see a new island appear. Clicking this island should modify the content of the page, injecting some credits about the people who built the site — a kind of hidden humans.txt :)

Now for something else that humanises an otherwise hard to reach subject... and obviously does it in a far superior way — *hats off*.
JavaScript : Clone an object in JavaScript with Doppel
by Developer @ pebbl.co.uk on Thursday, 9 May 2013
With all my recent work towards Describe.js there have been a few mini functionalities that I've been able to generalise, ExpReg was one, Doppel is another. I've seen many deep clone methods in my time, but for Describe I needed the option to change the way the cloning was accomplished on a per usage basis. This might be quite a specific use-case, but there's no harm in putting it up here as a separate piece of code.
Whilst the following design is obviously not optimal — calling a function for every clone operation is quite slow — it does offer a lot of flexibility and mean that external code can form part of the cloning process.
var objToClone, objDoppel;

objToClone = {'hello':{'abc':123}, 'world':{'def':'456'}};
objDoppel  = Doppel(objToClone);

console.log( objDoppel ); /// an output that looks like objToClone
console.log( objDoppel.test ); /// undefined

objToClone.test = 'added';

console.log( objDoppel.test ); /// 'added'
Doppel is hardwired to use Doppel.IMPOSTOR by default. This descriptor attempts to create clones that inherit from their origin — as shown above. If you wish to override this behaviour you could just modify Doppel.IMPOSTOR any way you like, or, you could pass in another descriptor:
var objToClone, objDoppel;

objToClone = {'hello':{'abc':123}, 'world':{'def':'456'}};
objDoppel  = Doppel(objToClone, Doppel.CLONE);

console.log( objDoppel.test ); /// undefined
objToClone.test = 'added';
console.log( objDoppel.test ); /// undefined
Essentially Doppel is a map function but for objects. If you so wished you could do something like this:
var objToClone, objDoppel;

objToClone = {'hello':{'abc':123}, 'world':{'def':'456'}};
objDoppel  = Doppel(objToClone, {
  'object' : function(){ return {}; }
  'string' : function(e){
    return e.target.replace('456', '654');
  }
});
Which would result in a cloned object but with 'def':'456' being changed to 'def':'654'. Anyway, it's a random bit of code that someone else might find useful, so here it is:
/**
 * Doppel 0.1
 *
 *  Doppel is a system that can clone an object in a tailored way.
 *
 *  @param obj       : the object to be cloned
 *  @param behaviour : an object containing type-keys which
 *                     describe what should be done for each
 *                     var type found. See Doppel.IMPOSTOR or
 *                     Doppel.CLONE for examples, you can pass
 *                     your own object too.
 *  @param recurse   : boolean if true will deep clone, if false
 *                     will only clone the object passed. (not
 *                     implemented fully yet, assume true)
 *
 *  @author Phil Glanville - 2013/05
 */
var Doppel = (function(){
  var g, describe, doppel, impostor, DoppelEvent;
  /// DoppelEvent mimics a similar implementation of an Event object
  /// an instance of this "event" is passed into each clone description
  /// method, giving quite a bit of useful information, and allowing
  /// that code to decide where the recursion stops.
  DoppelEvent = function(target, parent, property, path){
    /// the target object
    this.target = target;
    /// the parent of target
    this.parent = parent;
    /// property on the parent storing target
    this.property = property;
    /// a built recursive path of properties
    this.path = path;
    /// Doppel will continue to recurse if true
    this.recurse = true;
  };
  DoppelEvent.prototype.preventRecursion = function(){
    this.recurse = false;
  };
  DoppelEvent.prototype.allowRecursion = function(){
    this.recurse = true;
  };
  /// the actual recursive worker function
  g = function(obj, behaviour, recurse, work, parent, property, path){
    var r,i,e,t = describe && describe.type
      ? describe.type(obj)
      : typeof obj
    ;
    if ( recurse ) {
      e = new DoppelEvent(obj, parent, property, path);
      /// just in case we've come across this object before.
      /// @todo: would be good to find a more optimal way that
      /// doesn't rely on modifying any src or dst object.
      if ( (i=work.src.indexOf(obj)) !== -1 ||
           (i=work.dst.indexOf(obj)) !== -1 ) {
        return work.dst[i];
      }
    }
    /// create our doppel
    r = (i=behaviour[t]||behaviour['default']) ? i.call(this, e) : obj;
    /// store for checks next time around
    work.src.push( obj );
    work.dst.push( r );
    /// if we are still allowed to recurse
    if ( e.recurse ) {
      for( i in obj ) {
        r[i] = g(obj[i], behaviour, recurse, work, obj, i, path+'/'+i);
      }
    }
    return r;
  };
  /// the exposed function that will be Doppel()
  doppel = function(obj, behaviour, recurse, work){
    recurse = true; /// false mode is not fully implemented yet.
    describe = typeof describe !== 'undefined'
      ? describe
      : {type:function(o){return typeof o;}}
    ;
    if ( arguments.length === 2 ){
      if ( behaviour === true ) {
        behaviour = doppel.IMPOSTOR;
        recurse = true;
      }
      else if ( behaviour === false ) {
        behaviour = doppel.IMPOSTOR;
        recurse = false;
      }
      else {
        recurse = true;
      }
    }
    else if ( arguments.length === 1 ){
      recurse = true;
    }
    if ( !behaviour ){
      behaviour = doppel.IMPOSTOR;
    }
    if ( recurse ) {
      work = {src:[], dst:[]};
    }
    return g(obj, behaviour, recurse, work, null, null, '');
  }
  /**
   * using the impostor description means that each of your
   * clonable properties will inherit from the origin, but
   * will essentially be a new object in-themselves.
   */
  impostor = function(){};
  doppel.IMPOSTOR = {
    /// for objects, create a new instance with the origin inherited
    'object' : function(e){
      impostor.prototype = e.target; return new impostor();
    },
    /// please note function clone does not honour function.length
    'function' : function(e){
      return function(){e.target.apply(e.src, arguments);}
    },
    /// you could inherit an array from an array, but it would be weird
    'array' : function(e){
      return target.slice(0);
    },
    /// for anything else, return the origin
    'default' : function(e){
      e.preventRecursion();
      return e.target;
    }
  };
  /**
   * The Clone description will actually create new objects for clonable
   * items. These new items have no link to their origin what-so-ever.
   * This is a very simple clone, if you wish to perform cloning of
   * objects containing DOM Elements or other complex Native
   * constructs I'd recommend building your own description object.
   */
  doppel.CLONE = {
    /// for objects, new object
    'object' : function(e){
      return {};
    },
    /// for arrays, slice clone
    'array' : function(e){
      return e.target.slice(0);
    },
    /// for anything else, leave as it is
    'default' : function(e){
      e.preventRecursion();
      return e.target;
    }
  }
  return doppel;
})();
- Leave your comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
describe.js v0.4, 0.5 and 0.6 have all been, urm... skipped.
by Developer @ pebbl.co.uk on Saturday, 27 April 2013
Things have gone a little quiet on the describe.js front, and the reason for this is that the last three versions have failed to be finished, and so, have also failed to see the light of day. Mainly because I kept on coming up with better ideas, well at least according to my brain anyway.
So just to keep things going — until I actually post some code — I thought I'd report that I'm now working on version 0.7. There is a reason for these leaps, which I'll explain once I'm done, but it should mean that describe will be even more powerful and extensible than before.
You'll just have to take my word for it for the moment though.
- Leave your comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
I just put this miniature library together to help work with Regular Expressions in a cleaner and abstracted manner. It's pretty simple, but RegExp interaction in JavaScript has always been a little clunky in my opinion, so it doesn't take much to smooth things out a little.
/// example usage
var result =
  ExpReg(/\|/gi)
    .haystack('[believe|dont]|[either,way]')
    .replace(function(match, i){return '{'+i+'}';})
    .haystack()
;
/// result = '[believe{8}dont]{14}[either,way]'
Whilst the above may actually be shorter to type in pure JavaScript:
String('[believe|dont]|[either,way]')
  .replace(/\|?(\[[^\]]+\])/gi, function(match, i){
    return '{'+i+'}';
  })
;
.. the problem with the above is that it is completely different from the formation to step through items matched, for example:
var m, re = /\|?(\[[^\]]+\])/gi;
while( (m = re.exec('[believe|dont]|[either,way]')) ) {
  /// do whatever processing required here.
};
The main benefit of using ExpReg would be that the way of dealing with Regular Expressions is standardised, and all the RegExp objects that are created are remembered, so you can refer back to them quickly — useful in code that reuses expressions. Plus it's easy to add new methods that work in a builder fashion — similar to jQuery.
/// another example using a string instead of literal RegExp
ExpReg('/./gi')
  .haystack('this should match every letter')
  .each(function(match, i){alert(i)})
;

/// an example of mapping
var words =
  ExpReg(/\w+/gi)
    .haystack('this should match every word')
    .map(function(match){return match})
;
Just in case it comes in useful, here is the recently imagined source code of expreg.js :)
/**
 * ExpReg 0.1
 *
 *  ExpReg is just a simple RegExp wrapper that has some useful
 *  functions for dealing with Regular Expressions. This include
 *  is designed to work with require.js but can also operate as
 *  a normal js include.
 *
 *  @author Phil Glanville - 2013/05
 */
var ExpReg;
/// define not-exist fallback
(typeof define === 'undefined' &&
  (define=function(a){return (ExpReg = a())}));
/// hook into require.js
define(function(){
  "use strict";
  var global = {
    delims: new RegExp('^([^a-z0-9\s])(.+?)\\1([gimy]{0,4})$','i'),
    lookup: {}
  };
  /**
   * The outer wrapping constructor that will be exposed as ExpReg
   */
  var ExpReg = function(re, haystack){
    var t;
    if ( this instanceof ExpReg ) {
      if ( !global.lookup[re] ) {
        if ( re instanceof RegExp ) {
          global.lookup[re] = re;
        }
        else if ( (t = global.delims.exec(re)) ) {
          global.lookup[re] = new RegExp(t[2],t[3]);
        }
      }
      this.exp = global.lookup[re];
      this.source = haystack?haystack:'';
      this.matches = [];
      this.matched = false;
      this.reversed = false;
    }
    else {
      if ( typeof this == 'string' ) {
        return new ExpReg(re, ''+this);
      }
      else {
        return new ExpReg(re, haystack);
      }
    }
  };
  /**
   * Simple jQuery like attr function
   */
  ExpReg.prototype.attr = function( name, value ){
    if ( arguments.length == 2 ) {
      this.exp[name] = value;
    }
    else {
      return this.exp[name];
    }
  };
  /**
   * Define the haystack that the RegExp will search
   */
  ExpReg.prototype.haystack = function(string){
    if ( arguments.length && (typeof string == 'string') ) {
      this.source = string;
      this.matched = false;
      return this;
    }
    else {
      return this.source;
    }
  };
  /**
   * Return a particular matched item. A matched item will
   * be an object that contains a zero-indexed array of .groups
   * and an .offset property that gives the start of where the
   * match was found.
   */
  ExpReg.prototype.item = function(n){
    if ( arguments.length == 0 || n === undefined || n === null ) {
      return this.matches;
    }
    else if ( n < 0 ) {
      return this.matches[this.matches.length+n];
    }
    else if ( n < this.matches.length ) {
      return this.matches[n];
    }
    else {
      return null;
    }
  };
  /**
   *
   */
  ExpReg.prototype.findAll = function(){
    /// remove previously found items
    this.matches.length = 0;
    /// reset and scan
    var groups; this.exp.lastIndex = 0;
    /// if we are global we can findAll
    if ( this.exp.global ) {
      while( (groups = this.exp.exec(this.source)) ) {
        this.matches[this.matches.length] = {
          groups: groups,
          offset: this.exp.lastIndex-groups[0].length
        };
      }
    }
    /// if not global, match the first and stop
    else {
      this.matches[this.matches.length] = {
        groups: (groups = this.exp.exec(this.source)),
        offset: this.exp.lastIndex-groups[0].length
      };
    }
    ///
    this.matched = true;
  };
  /**
   * Replace current selection with either string or result of callback
   */
  ExpReg.prototype.replace = function(param){
    if ( !this.matched ) { this.findAll(); }
    if ( this.matches.length ) {
      if ( typeof param == 'string' ) {
        this.source = this.source.replace(this.exp, param);
      }
      else if ( param.call ) {
        var exrg = this;
        this.source = this.source
          .replace(this.exp, function(a,b){return param(a,b,exrg)});
      }
    }
    return this;
  };
  /**
   * Call a callback for each match found
   */
  ExpReg.prototype.each = function(callback){
    if ( !this.matched ) { this.findAll(); }
    if ( this.matches.length ) {
      var i, l = this.matches.length;
      for( i = 0; i < l; i++ ) {
        callback.call(this, this.matches[i], i, this);
      }
    }
    return this;
  };
  /**
   * Map the matches to an array
   */
  ExpReg.prototype.map = function(callback){
    var a = [];
    if ( !this.matched ) { this.findAll(); }
    if ( this.matches.length ) {
      var i, l = this.matches.length;
      if( typeof callback == 'undefined' ) { callback = 1; }
      if ( callback.call ) {
        for( i = 0; i < l; i++ ) {
          a[i] = callback.call(this, this.matches[i], i, this);
        }
      }
      else {
        for( i = 0; i < l; i++ ) {
          if ( this.matches[i] &&
               typeof this.matches[i].groups[callback] != 'undefined' ){
            a[i] = this.matches[i].groups[callback];
          }
        }
      }
    }
    return a;
  };
  /**
   * wrap the matches with strings
   */
  ExpReg.prototype.wrap = function(pre, post){
    this.replace(function(match){
      return pre+match+post;
    });
    return this;
  };
  ExpReg.prototype.reverse = function(){
    if ( !this.matched ) { this.findAll(); }
    this.matches.reverse();
    this.reversed = !this.reversed;
    return this;
  };
  /**
   * debug log
   */
  ExpReg.prototype.log = function(pre, post){
    this.each(function(match, i){
      console.log(i, match);
    });
    return this;
  };
  String.prototype.ExpReg = ExpReg;
  return ExpReg;
});
/// remove our temporary define fallback
(ExpReg) && (define = undefined);
- Leave your comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
Centre Image : The strange combination of position absolute, margin auto and an image tag
by Developer @ pebbl.co.uk on Thursday, 25 April 2013
Just recently I was charged with the task of upgrading the Slideshow ability on the Tate's website, basically finishing off the work so that it could display more than just images, and to finalise it's mobile support. Most of the work was quite straightforward and entailed reverting some of the previous bespoke modifications made to the default Flexslider plugin, and then enhancing the out-of-the-box functionality with things like full-screen mode, and managing audio or video files that might be contained within.
Stop it and tidy up
One of the main improvements I made was to try and get things working with as little JavaScript as possible, this meant refactoring the CSS somewhat, and due to not having worked closely with CSS for the last year — save for the odd stackoverflow answer — I was quickly reminded just how frustrating-a-language CSS is to debug and repair... especially in it's pure form, outside of any compilation framework like LESS.
Anyway, re-realisations aside, I got pretty much everything working via CSS save for two issues. The first of these problems was the age old annoyance of how to centre an element in the middle of a container on both the vertical and the horizontal. Now I've been using CSS since the early days — if you could refer to them as early — so I'm quite aware of the different vertical alignment tricks that can be employed. I was also aware that the only way(s) I knew of to get an element of unknown or variable dimensions to centre was either to use a table, display:table, or use a background-image instead (at least for images anyway). Any one of these would have taken some crowbarring to get working harmoniously with the slideshow system. Unfortunately, every one of my slideshow images had variable dimensions, which not only varied depending on itself, but was also responsive to the display size... so I had to find some nicer way of doing it.
Solution?
Considering the fact that the well known browsers are now developing at a rate of knots, I decided that there must be a better way by now. Obviously I could have used flexbox, but it's fluctuating and unreliable support would have meant more headaches in testing than I had time for. So I spent quite a bit of time searching around, finding pretty much all the ways I already knew about, until I stumbled upon this random suggestion:
img { position:absolute; left:0;top:0;right:0;bottom:0; margin:auto; }
At first glance that snippet made no sense to me, and I almost automatically dismissed it as nonsense. I'm quite glad I ignored my first thoughts however and tested it out, because — at least for every user agent I checked — it did exactly what I needed. Now, if anyone can explain why this has been built in, and why images should behave differently to any other element, I'd be interested to hear... until then I'll just mark it down to another strange oddity in the interpretation of the rather wholly strange language/construct that is CSS.
- Leave your comment • Category: Coding, HTML and CSS
- Share on Twitter, Facebook, Delicious, Digg, Reddit
Internet Explorer Detection : The power of conditional comments but via jQuery
by Developer @ pebbl.co.uk on Wednesday, 24 April 2013
I came across a situation the other day where I needed a specific browser check (IE7 or less), there wasn't a particular testable feature to hand that would do and I didn't have access to the markup. My usual fix for Internet Explorer specific bugs is to use conditional comments, they do exactly what it says on the tin, however.. not having access to the page markup thwarted this otherwise quick and easy solution.
Rather than falling back to tenuous agent string checking — particularly worrying when it comes to specific version number checks — or bashing my head against multiple feature tests that could be invalidated in the future, I thought the following implementation would be no less mad, and maybe even slightly useful:
var isOldIE = function(query){
  return $('<!--['+(query||'if lte IE 7')+']>OLDIE<![endif]-->')
    .text() === 'OLDIE'
  ;
}
Make of it what you will, but I rather like it... even though it is hideous from an optimisation point of view.
- Leave your comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
After having a bit of time off to wander around Thailand, and finding that — despite having lovely people, beaches, street food, temples and sea life — that the country is drowning in vehicles and unwalkable roads.. this meant there were a few days of relaxing near my laptop. So I took the time to code in the sun and do some extra work with describe.js. In doing so I notice a few problems, which I've now tried to rectify.
- Collections only worked for constructors with one method, the foolish mistake of relying on a variable referenced from within a loop.
- The 'private' tag was working based on the constructor, so each instance of a constructor was sharing the same private object. Doh!
- The 'private' methods were attached (as wanted) to the ._ object, however this meant that 'this' inside a private method refered to the _ object, rather than the constructed instance.
So, I have now repaired these issues, which should definitely speed up development in my other projects. At the same time I've also added a few extra abilities:
- Getters and Setters — two new tags exists by default, get and set. These utilise the __defineGetter__ and __defineSetter__ methods, if the browser supports them. The upshot of this is that you can now create getter and setter attributes, that also support type overloading.
- Improved support for merging or wrapping functions — This was a byproduct of the fixes. There are now the following methods: merge, unmerge, wrap and unwrap.
- Rewrote the tag/plugin handling — this was mainly to fix the private issues above, but now gives the coder a choice to implement a tag/plugin method on the constructor or on the instance (the choice is made by creating a tag function of either 3 or 4 arguments). Implemented on the constructor the prototype object is used (saving resources), implemented on the instance (all private methods use this) the methods are specifically applied to the instance's private object.
- I've worked out many of the bugs with regards to properties (before describe only concerned itself with methods). So, now it is possible to create constructors with simple base type attributes... rather silly not to be able to support this in the first place.
Before I go...
I say 0.4ish because there is one major issue that I still hope to fix before uploading the new version, this is the good old multiple inheritance system. This will be the fourth rewrite of this particular bit of code, it's complicated, but I hope to simplify things and stop trying to be so clever (mainly because clever always causes issues unless you've managed to discover perfection lying around somewhere).
I think I'm going to go the same way as a number of other libraries and just use a shallow copy system for the inheritance, rather than relying on a dynamically morphing prototype chain. The reason for this is that I seem to be using the prototype chain more and more with my work in other projects, and the current system is getting in the way. I generally don't need the power of inheritance anyway, just the power of mixins, which is what a shallow copy system would provide.
I guess what I'm saying is there will be an update shortly... so watch the skies, or something.
Oh, a few more other improvements that are in the pipe line:
- Collections don't support Getters and Setters, but they will do.
- Also, I need to work out a way of describing tag behaviour when using multiple tags. For example, currently specifying 'private get methodName' or 'private set methodName' does not create a private getter or setter. Instead it creates a private method called methodName and a public getter/setter called methodName too.
- One comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
Just a quick update to say that describe.js—whilst still supporting type-based method overloading—now supports a few extra abilities:
- You can now define optional parameters using tilde ~
- You can now create collections for constructors built by describe.make
Collections
Creating a collection is as easy as the following:
var Example = describe.make({
  'method': function(){
    alert(123);
  }
});

var collection = new Example.collection();
    collection.push( new Example() );
    collection.push( new Example() );
    collection.push( new Example() );

collection.method(); /// this will trigger alert(123) three times
This is only the basic collection implementation that I wanted to build, I need to extend the collection manipulation methods i.e. allowing for merging, filtering or collecting collections, plus I have a few more useful ideas in this regard.
Optional parameters
Optional parameters have now been reinstated, and can be implemented in the following ways:
var Example = describe.make({
  'methodA [string,~number]': function(str,num){
    console.log(arguments);
  },
  'methodB [string,number]|[string]': function(str,num){
    console.log(arguments);
  },
  'methodC [string,~number,number]': function(str,n1,n2){
    console.log(arguments);
  },
  'methodD [string,~number,~number]': function(str,n1,n2){
    console.log(arguments);
  }
});
Using [string,~number] is identical to [string,number]|[string] which is identical to creating two methods with the same name (but with differing type arguments) which execute the same function.
The difference between 'methodC [string,~number,number]' and 'methodD [string,~number,~number]' is that the following method lookups will be created inside the constructor:
/**
 * [string,~number,number] will generate:
 *
 *   [string]
 *   [string,number,number]
 *
 * [string,~number,~number] will generate:
 *
 *   [string]
 *   [string,number]
 *   [string,number,number]
 */
Next steps?
I'd like to implement a few more functional "tags" that will take advantage of the new getter and setter implementations, and just generally focus on constructor properties rather than methods, as I haven't really looked at supporting them yet.
var Example = describe.make({
  'set hello': function(v){
    this._.hello = v;
  },
  'get hello': function(){
    return this._.hello;
  }
});

var a = new Example();
    a.hello = 'world';
Other tag ideas...
once
A tag that assigns a method to a constructor, but once called, the method is removed.
event
Tags every method that is used as an event listener, allowing your own code to step in and modify the event object before being used by your constructor code.
moz, opera, webkit, ms
Only assigns the method if the browser is a particular type.
- Leave your comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
About
Whilst working on this pebbl rewrite I've been developing a system to help me sketch object structures in JavaScript, considering it seems to have worked quite well, I thought I'd write a bit about the power of describing what you want; rather than maybe actually having it perfect right away.
For me, there are two main issues with regard to getting anything developed. The first is normally the amount of time I have free to devote to the project—gone are the days where I had weeks and weeks to code and experiment—this in itself is the main cause of my second issue; which is to always make sure code can be easily remerged, revamped and made, basically, future-indifferent... all because by the time I've started to get anywhere, it's normally time to reassess available technologies again.
CURSE YOU PROGRESS!
The plan...
So the above are my main reasons for gravitating towards scripting languages, and those specifically that allow for greater sketching and expression -- like JavaScript, Python, Lisp -- because they allow me to move faster in this crazy world. However there is always room for improvement, and after having worked on a large number of projects over the last 13 years I've been slowly aggregating a list of all the features that I expect to have in my new projects:
- Constructors should be easily described in a standardised way.
- Constructors should support multiple inheritance.
- Constructors should support method overloading.
- Constructors should support a way to "categorise" methods, taking on the power of "tagging"
- Constructors should support the power of collections, like how jQuery can "select" multiple elements and apply methods as a group.
- The structure of constructors should be separate from their implementation.
- The system should tie into some kind of tearDown management.
- The system should be extendable and have future support for the new object methods i.e. getters, setters and proxies
So, with the above in mind I constructed a system that allowed me to describe what I wanted before I had actually implemented everything.
Sorry, the phrase "cargo bay doors" is not in my lexicon
I had already decided that I wanted method overloading despite the obvious drain on performance. But then I've never liked optimising when it detracts from development speed, and considering one of my most repeated tasks was writing headers for functions that could accept a gaggle of differing arguments (Is there a collective noun for arguments?), I wasn't about to let a few milliseconds get in the way of happier coding. Besides, compared to other faux-overloading implementations I've seen around, I thought this one had merit and was possibly a fast way of doing type-based overloading:
var Example = describe.make({

  /// called when a new instance is created
  'construct': function(){

  },

  /// called if passed an object and a number
  'method [object,number]': function(obj,num){
    return 1;
  },

  /// called if passed a function and a number
  'method [function,number]': function(fun,num){
    return 2;
  },

  /// called if passed a function and anything else
  'method [function,*]': function(fun,any){
    return 3;
  }

});

var a = new Example();
    a.method({},123);          /// returns 1
    a.method(function(){},123) /// returns 2
    a.method(function(){},{})  /// returns 3
    a.method()                 /// trips a console error
- useful note :- basically the system works by processing each 'method key' and creating a lookup hash object, keyed on the string of types. Then whenever a method is called the arguments are converted into their own string of types - using a mixture of duck typing, typeof and instanceof - which is then used to look the function up from the hash. I have yet to put some real optimisation work in yet, but it already seems to operate quick enough for my needs.
As the dangerously astute may notice, the above constructor design ticks quite a few of my requested features. The structure is kept separate from the actual constructor implementation (that happens behind the scenes and means it's readily changeable), the construction follows a standard, the method key containing type definitions allows me to very visibly build overloaded methods whilst still allowing for easy change of implementation later on—basically if JS2 is ever released ;)
2X4B
What the above design doesn't make obvious is that by using a framework to construct my constructors, I can easily tie in tearDown management (e.g. introduce a 'deconstruct' standard), plus I can extend how the method keys are parsed, for example another extra that comes with the describe system—in it's current form—is the following:
var Example2 = describe.make({

  /// all methods are "public" by default, unless otherwise stated
  'public publicMethod': function(){

  },

  /// "static" methods are added to the constructor instead
  'static staticMethod': function(){

  },

  /// kept away from the public object so as to keep a clean interface
  /// not truly private however - although is open to future support.
  'private privateMethod': function(){

    /// to call this method access the ._ attribute
    this._.privateMethod();

  },

});

var b = new Example2();
    b.publicMethod();     /// all methods are "public" by default
    p.privateMethod();    /// will be undefined so will trigger an error

Example2.staticMethod();  /// "static" adds to the constructor instead
Whilst many may frown at the very suggestion of needing to "parse" anything, especially strings, I can at least argue in my defence that this parsing only occurs at set-up time. Once the constructor has been built I try an minimise the amount of processing that occurs. Obviously if you are looking for blistering performance, you don't try and bend a language to do things it's not designed for. For my own piffling forays into the scripting world though, this system works, and that's all I'm bothered about.
Back to reality
Ok, before you reach for whatever your preferred social commenting medium is, I've already thought about the problem you're first thinking of... probably not the second or third, but hey.... The first thing I'm sure others may point out is that you can't rely on typeof in all situations—those who've tried type checking arrays will be well aware of JavaScript's fickleness when it comes to types. That's why, in the spirit of future-indifference, all the type checking is run through describe.type - a function that mainly relies on duck testing (faster in my opinion that type checking, I'm not a processor though, so my opinion probably doesn't count). By keeping this check as an exposed function it is in-keeping with extensibility and will allow anyone to override it's workings—if they like.
- useful note :- describe.type checks all objects for a .toDescribe() method. This operates just like .toString() save for the fact it should return the type of the object - rather than it's value - as a string. If this method exists describe.type will use it's returned value instead of calculating the value itself.
In fact I've tried to keep every part of describe exposed so that it's easy to override. All I want is the framework, filled out with code that I'm happy with. Others may still find the framework useful, but hate my implementation. Therefore they can override whatever they like, this also includes how the private, public and static handling is implemented. They need look no further that the describe.tags object:
describe.tags = {
  'public': function( obj, data, workings ){
    obj.prototype[data.name] = data.prop;
  },
  'private': function( obj, data, workings ){
    if ( !obj.prototype._ ) {
      obj.prototype._ = workings._ = {};
    }
    obj.prototype._[data.name] = data.prop;
  },
  'static': function( obj, data, workings ){
    obj[data.name] = data.prop;
  }
};
As you might have discerned from the above, all you need to invent a new method "tag" is to add it to this object. At the point of creating the constructor these tag methods are called on each method that is tagged, obj refers to the constructor, data is a simple collection that describes the method or property being added; workings is a private object that can be used between tag methods as the constructor is formulated. Put simply, this system really does allow for quite a lot of control over how your constructors are put together. For example, in one of my projects I've developed a new tag called 'on' which automatically bind's each method as an event handler to the new instance being created.
Download and documentation
Describe.js is still a work in progress. In the not-too-distant-future I hope to have the following merged into the codebase:
- Allow for instances to be easily be grouped together and manipulated simultaneously i.e. just like jQuery can wrap multiple elements.
- Better implementation of multiple inheritance - describe.make does currently support this, but I'm looking to improve the implementation.
- Re-implement support for optional arguments. I had this in a previous version, however it got removed in the last rewrite.
For the moment though, describe.js works. So, if you're interested, you may wish to know about a few other useful methods bundled into the 8Kb that currently makes up describe.min.js:
describe( object )                          /* [string] */
describe( object, mode    /* [number] */ )  /* [string] */
describe( object, options /* [object] */ )  /* [mixed] */
describe( object, options, mode )           /* [mixed] */

  /**
   * describe() the core function is first and foremost a
   * type guessing function. Pass in an object and it'll try
   * and tell you what it is, in string form. Currently supports
   * the following:
   *
   *  string, number, boolean, function
   *  array, object
   *  event, window, document, element
   *
   * jQuery objects are treated as arrays, but it would be easy
   * to create a version that explicitly reported 'jquery'
   *
   * describe() also supports subtle changes in mode. For example:
   *
   * describe([123])                    /// returns 'array'
   * describe([123], describe.ARRAYS)   /// returns '[number]'
   * describe([[123]], describe.ARRAYS) /// returns '[[number]]'
   * describe([[123]], describe.ARGS)   /// returns '[array]'
   */
describe.make(
  descriptor /* [object] */
)

describe.make(
  extensions /* [array]  */,
  descriptor /* [object] */
)

  /**
   * describe.make() as shown above constructs constructors.
   *
   * describe.make() uses describe's power but wraps it in a
   * constructor/class-like object. The result is that it becomes
   * easy to describe class-like constructors that support method
   * overloading and 'method tagging' which allows you to create
   * methods with different abilities.
   *
   * describe.make() supports inheritance using the extensions
   * array. Just pass the constructors listed in an array that you
   * wish your new constructor to extend. I hope to rework this
   * implementation shortly, as it's not quite what I want atm.
   *
   * returns the a constructor method [function]
   */
describe.construct(
  constructor /* [function] */,
  arguments   /* [array]    */
)

  /**
   * describe.construct() allows for the creation of new instances
   * of a constructor in a programmatical way, allowing for variable
   * arguments.
   *
   * returns a new instance of the constructor [object]
   */
describe.proxy(
  source          /* [object]   */,
  method          /* [string]   */,
  returnFunction  /* [function] */,
  augmentFunction /* [function] */
)

  /**
   * describe.proxy() returns a method that proxies a method
   * from the source object. You also have the option of
   * passing a function that can be used to modify the return
   * value (returnFunction), or passing a method that can
   * modify the way the proxy method is called (augmentFunction).
   * describe.proxy is used to power describe.borrow()
   *
   * returns the proxied method [function]
   */
describe.borrow(
  source          /* [object]       */,
  methods         /* [array|string] */,
  returnFunction  /* [function]     */,
  augmentFunction /* [function]     */,
  destination     /* [object]       */
)

  /**
   * describe.borrow() allows a destination object to "borrow"
   * a method or methods from another source object. A simple
   * example would be to have a describe'd class borrow the
   * bind and unbind methods of jQuery.
   *
   * If no destination object is specified borrow works on the
   * current 'this' object.
   *
   * returns [undefined]
   */

describe.merge
describe.merge(
  source     /* [function] */,
  additional /* [function] */
)

  /**
   * describe.merge() is a relatively experimental idea at the
   * moment. It allows for a method to be merged with other
   * method(s). At the time of calling, all methods are fired.
   * currently it is only the original method's return-value that
   * gets returned, but in the future I may improve this to handle
   * a collection of return values at request.
   *
   * A simple usage example would be to late-bind an additional
   * function of code to a constructors 'construct' method.
   *
   * returns the merged [function]
   */
Example usage
Just to get the ball rolling, here is a quick example. This shows the use of namespacing to keep your describe configuration local to your code:
<script src="describe.min.js"></script>
<script>

  (function(describe){

    var MyConstructor = describe.make({
      'construct': function(){},
      'exampleMethod [string]': function(str){},
      'exampleMethod [number]': function(num){},
      'exampleMethod [object,array]': function(obj,arr){},
      'exampleMethod [*]': function(anything){}
    });

  })(describe.namespaced('my_name'));

</script>
- Leave your comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
It's rather unbelivable, but I've actually managed to make some headway on Pebbl during the Christmas festivities... Oh aaaaand a merry new year by the way! So in preparation of my birthday happening in a galaxy not too far away I'd though I'd actually put something up to show that I haven't been sitting on my hands, or at least not consistently.
Be warned this is just a code demo
Obviously it doesn't appear like much at the moment--I didn't want to give too much away--but the astute of you out there will notice a few things.
- There isn't a shred of the original code powering this demo page.
- There are many shreds of original ideas woven together and put to good use.
- The code has evolved and benefited from another year of on/off development.
- The game will still be JS/HTML5 powered.
- The hybridisation between canvas and the DOM is even more involved.
- It supports Box2D for it's physical interactions!
- It supports require.js for the asyncronous loading.
- The backend (that you don't see here yet) is powered by node.js.
- I've ripped out my previous 'class-like' system, burnt it, blended it, spread it on toast, stuck it to the ceiling... and brought it back from the edge of the cornicing in the form of describe.js
As I stated in a previous post, the idea of this rewrite is to try and pull things away from being purely canvas based. Mainly because I found that the canvas wasn't fast enough across all the devices I tested -- whereas the dom allowed for quite smooth and fast animation. This I've achieved whilst still leaving room to switch back to a full canvas render if the future processors of this world decide to get any faster... it's likely that they will.
So now the system operates at quite a few different levels:
- The Box2D Physics world powers most movement.
- For non-physics based animation jQuery dom manipulation is used.
- For key-frame based animation background images and spritesheets are used on dom elements
- For sprites that can benefit from cloning, canvas is used instead of DOM.
- For masked content, pixel and lighting effects, separate canvas elements are used like dom elements.
- Everything is tied into jQuery's bespoke event system.
- With a few homemade jQuery plugins Sprites can be grouped and controlled via CSS selectors.
- Where possible I will try and use the up and coming CSS filters to achive effects in the game, and possibly fall back to SVG effects in older versions of FireFox.
- All sprites support controller objects that can be user, animation or bot controlled.
All I have left now is to rework the Map loading code so that pages can be loaded (just like in the original demo, by walking off screen) and then tie in the backend Node.js code so that a user can have an account and their progress can be logged. All in all 2012 was quite a good year ;)
It's a similar pattern that arises in many programming languages - the need for a function to accept differing structures of arguments - and is the reason why certain languages have built-in support for this behaviour, with the use of functional overloading.
In JavaScript however, no such ability exists - and with each of my pure js projects over the last 4 or 5 years, I kept getting rather bored with writing and rewriting the same kind of checks at the top of a function to handle a range of different ways the entity could be called.
So I've been playing with a solution to this idea for a while, but each of my implementations always felt like over coding the issue. JavaScript should be light, quick and powerful - most of what I came up with wasn't.
However, having reached the same situation for the umpteenth time. I finally threw together a solution that seems to be exactly what I've needed, so far at least, and is a lot simpler than previous versions:
var describe = (function(){
  var describe = function( obj, opt, mod, looped ){
    var m,i,s,t = describe.type(obj), w = describe.type(opt);
    if ( w === 'number' || w === 'array' ) {
      mod = opt; w = opt = null;
    }
    if ( describe.type( mod ) == 'number' ) {
      m = mod
    }
    else {
      m = describe.TYPES
    };
    if ( (t === 'array') && (!looped || m & describe.ARRAYS) ) {
      s = '';
      for ( i in obj ) {
        if ( obj.hasOwnProperty && !obj.hasOwnProperty(i) ) {continue;};
        s += (s?',':'')
          + describe(obj[i], mod && mod[i] ? mod[i] : m, null, true);
      }
      t = '['+s+']';
      m = null;
    }
    if ( w === 'object' ) {
      if ( opt[t] ) {
        opt[t].apply(describe,obj);
      }
      else if (opt['*']) {
        opt['*'].apply(describe,obj);
      }
    }
    else if ( m ) {
      s = '';
      if ( m & describe.VALUES ) {
        s += String(obj);
      }
      else {
        s += (s?':':'') + t;
      }
      t = s;
    }
    return t;
  }
  describe.TYPES = 1;
  describe.VALUES = 2;
  describe.ARRAYS = 4;
  describe.type = function(obj,t){
    if (
      (t = typeof obj) &&
      t === 'string' ||
      t === 'number' ||
      t === 'boolean' ||
      t === 'function' ) {
      /// ILB
    }
    else if ( t == 'undefined' || obj === null ) {
      t = 'null';
    }
    else if(
      (t == 'array') ||
      (window.Array && obj instanceof Array) ||
      (obj.join && obj.slice && obj.unshift) ||
      (obj[0] && obj.length) ||
      (window.jQuery && obj instanceof jQuery)
    ){
      t = 'array';
    }
    else if (
      (obj.call && obj.apply) ||
      (window.Function && obj instanceof Function)
    ){
      t = 'function';
    }
    else if ( obj.location && obj.open ){
      t = 'window';
    }
    else if ( obj.getElementById ){
      t = 'document';
    }
    else if ( obj.getElementsByTagName ){
      t = 'element';
    }
    return t;
  }
  return describe;
})();
The idea is a simple one, which could (and will) be improved over time. It's based mainly on type checking, but it can also handle value checking. A basic implementation would be as follows:
var my_function_to_call = function(a,b,c,d){

  describe(arguments,{
    '[object,object]':function(a,b){
      /// do what you need to set-up if you get two objects
    },
    '[string,object,number]':function(a,b,c){
      /// do what you need to set-up given a string, object and a number
    }
    '*':function(a,b){
      /// fallback for anything else
    }
  });

}
The above makes for much easier reading, and even though this example does create and destroy several temporary functions with each my_function_to_call() -- for most of my core functions that might only get called once or twice it works very well. Obviously you could optimise by keeping your second parameter for describe defined outside of my_function_to_call, but if you are really looking for optimal high-frequency code you should be using the standard js methods of type checking.
A few other ways the code can be used:
var test = function(name, step){

  describe(arguments,{
    '[helloworld:string,123:number]':function(a,b){
      /// do something when specific values and types are passed
    },
  }, describe.VALUES | describe.TYPES);

  describe(arguments,{
    '[helloworld,123]':function(a,b){
      /// do something when specific values are passed
    },
  }, describe.VALUES);

  describe(arguments,{
    '[helloworld,number]':function(a,b){
      /// do something when a specific value and specific type is passed
    },
  }, [describe.VALUES, describe.TYPES]);

}

test('helloworld', 10);
The astute readers out there will notice that this function basically just describes whatever object is passed into it, in simple terms. The secondary parameter is a bonus, as it allows the generated descriptive string to be checked against an object of methods. So you can use the above function just to aid in type checking:
if ( describe(param) == 'array' ) {
  /// do something with an array - the code uses a duck test
  /// so if something quacks like an array - i.e. jQuery it'll
  /// be called an array. I do have another version of this code
  /// that is specifically designed to return jQuery for jQuery objs.
}
This is just a starting out point, but so far I like the way things are working, so I shall continue...
Below you will find a minimized version of the above code:
var describe=(function(){var a=function(b,c,d,e){var f,g,h,i=a.type(b),j=a.type(c);
if(j==="number"||j==="array"){d=c;j=c=null}if(a.type(d)=="number"){f=d}
else{f=a.TYPES}if(i==="array"&&(!e||f&a.ARRAYS)){h="";
for(g in b){if(b.hasOwnProperty&&!b.hasOwnProperty(g)){continue}
h+=(h?",":"")+a(b[g],d&&d[g]?d[g]:f,null,true)}i="["+h+"]";f=null}
if(j==="object"){if(c[i]){c[i].apply(a,b)}else if(c["*"]){c["*"].apply(a,b)}}
else if(f){h="";if(f&a.VALUES){h+=String(b)}else{h+=(h?":":"")+i}i=h}
return i};a.TYPES=1;a.VALUES=2;a.ARRAYS=4;a.type=function(a,b){
if((b=typeof a)&&b==="string"||b==="number"||b==="boolean"||b==="function"){}
else if(b=="undefined"||b===null){b="null"}
else if(b=="array"||window.Array&&a instanceof Array||
a.join&&a.slice&&a.unshift||a[0]&&a.length||
window.jQuery&&a instanceof jQuery){b="array"}
else if(a.call&&a.apply||window.Function&&a instanceof Function){b="function"}
else if(a.location&&a.open){b="window"}else if(a.getElementById){b="document"}
else if(a.getElementsByTagName){b="element"}return b};return a})();
- One comment • Category: Coding, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
Bug with PHPUnit_Extensions_SeleniumTestCase
by Developer @ pebbl.co.uk on Wednesday, 26 September 2012
Over the last few years I've been constantly surrounded by chatter with regard to Selenium, but had never been in a position to try it out. Yesterday that changed when Tate stated the need to have as near to continous integration as possible with the on-going enhancements to their core website.
So, this has led to lots of interesting learning and reading up on something that has - until now - only really been a buzzword for me :)
Unfortunately my first foray into this area led me straight to a rather annoying bug in a particular PHPUnit extension designed to integrate a PHP script with Selenium. Basically I set about doing what most coders would do when presented with an Object Orientated architecture, I attempted to extend PHPUnit_Extensions_SeleniumTestCase with my own functionality.
Initially everything seemed to work as expected... that is until one of my Selenium tests generated an error. Rather than a helpful error message, my script bugged out with the following unhelpful error:
Argument 5 passed to PHPUnit_Framework_Error::__construct()
must be an instance of Exception, array given
On a closer look into the problem it seems that PHPUnit_Framework_Error.php has been upgraded, however the code in PHPUnit_Extensions_SeleniumTestCase.php hasn't.
class PHPUnit_Framework_Error extends Exception
{
    /**
     * Constructor.
     *
     * @param  string     $message
     * @param  integer    $code
     * @param  string     $file
     * @param  integer    $line
     * @param  Exception  $previous
     */
    public function __construct($message,
                                $code,
                                $file,
                                $line,
                                Exception $previous = NULL)
    {
        parent::__construct($message, $code, $previous);

        $this->file  = $file;
        $this->line  = $line;
    }
}
The fifth argument has been changed to expect an Exception object, whereas, whenever a new PHPUnit_Framework_Error is called into existence from PHPUnit_SeleniumTestCase.php, you get:
throw new PHPUnit_Framework_Error($buffer,
                                  $e->getCode(),
                                  $e->getFile(),
                                  $e->getLine(),
                                  $e->getTrace());
The last parameter is incorrect, it should be:
throw new PHPUnit_Framework_Error($buffer,
                                  $e->getCode(),
                                  $e->getFile(),
                                  $e->getLine(),
                                  $e);
Or at least changing it to the above fixes the issues I was experiencing, now my code warns about errors correctly. Just in case it's useful to anyone out there :)
It's been a while since I last uttered a word on this here platform. Just so you know, I haven't given up... and I am still working away at Pebbl behind the scenes of this rather lacking yet odd demo site.
On another note though - outside of Pebbl world - I've been focusing quite a bit again on good ol' PHP... I'd manage to escape real PHP work for a little bit, but now it is back with 'a vengeance' and is involving me in all sorts of situations where I need to search through large structures to find small bits of information... Small bits of information that could be anywhere (long story).
To save myself a lot of manual labour - something which computers are supposed to help with - I came up with a nice little function to help me out, hence the reason for the post, and the reason for the Pastie link below:
http://pastie.org/4694918 (found a bug! fixed in the next link)
Yes, it is true... and no I haven't converted Pebbl from a JavaScript game in to a bespoke CMS platform or anything mad... Instead I've decided to modify my Canvas Theory library so that it no longer uses Canvas as it's primary rendering system. Now this might seem a little bit illogical for something that started out as a Canvas & HTML5 experiment, but trust me I know what I'm doing ;) The new off-shoot library will be known as SpriteTheory.
Reasons?
Why? you may ask... well actually you most probably wont, but considering Blogs are a bit pointless if there is no need for explanation I'll ignore that statistical likelihood. The main reason for the change is purely due to optimisation, and also so I can prove wrong those out there who deem Flash (and it's contemporaries) to be extinct.
Most coders who claim Flash to be a dead parrot, and that HTML5 is the saving grace of all, have not tried to recreate what is achievable with Flash in HTML5. They have most probably just bundled together a nice slideshow and said "Hey... what was it we needed Flash for again?"... worryingly, some may not have even got that far and prefer to just mimic statements made by others. The fact of the matter is that Flash does a hell of a lot more that what is possible with pure HTML5 & JS - and it does it a hell of a lot faster. But anyways, before I start going off on one, I'll get to the point. I am not pro any particular technology, I just state what is and isn't possible at the moment (that may change of course). What seems not to be acceptably possible currently is to get good performance when running a sprite system using a full-screen canvas element across all the top browsers.
Excuses...
What...? I hear the non-existent critics expel in chorus. Not fast enough? But what about all the game emulators out on the web... or the 3D demos? Well, it seems that nearly all the emulators I've seen operate on a pixel by pixel basis (or small sprites) and usually on canvas elements with dimensions of about 320x200... tiny. This is not what I wanted for Pebbl, I wanted the full area of the browser to be in-use. And well, any 3D environment I've come across using Canvas is either hardware excelerated (using 3D context) or put together in a very specific and limited way... I wanted Pebbl to be 2D and not limited at all.
After spending some time developing a Canvas specific library, I found that no matter how optimal my code was, the clearRect and drawImage methods of the Canvas Element were taking most of the rendering time. So no matter how good I was with my code, I'd still always be limited by something I couldn't alter. As I said before this may change in the future, we shall see. But after finding this out, and making sure I was using my own "only draw what's needed" and "only clear what's changed" system, I was still finding slow-down after implementing less than half of what I wanted to. I was also finding that the frame-rate was wildly different across each browser. This was not good enough, plus it also seemed a bit pointless, when browsers implement their own redraw system anyway.
Conclusions...
So, after a bit of kicking myself for trying to re-invent the wheel and not going for the more elegant solution in the first place, my new library now works based on old-school absolutely positioned HTML Elements with CSS Transformations and Canvas enhancements. The Sprite interface is nearly almost the same, so I shouldn't have to do to much rewriting, all I have to do is dump most of the Canvas draw stuff, and optimise for dealing with HTML Elements instead. No more redraw problems, or slow-down. My main reason for going down the Canvas route in the first place was because I wanted to have pixel-perfect collisions and pixel affects. Considering most browsers handle the creation of many small Canvas elements with ease, and allow these Elements to be treated like any old DIV Element, I don't need to use a full Canvas "Stage" as-it-were and can instead treat each Sprite that needs the advanced methods as a separate Canvas element.
- Leave your comment • Category: Coding, Game Dev, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
Webkit: Canvas and background-size performance problems
by Developer @ pebbl.co.uk on Sunday, 2 October 2011
At last...! I've been searching through my code for Pebbl to try and find a specific Webkit performance drain, focussing mainly on the JavaScript, to see if I was doing anything odd. Due to the nature of Pebbl (being a HTML5 Canvas game) I was assuming that the problem was something that I had introduced in to my js Library CanvasTheory. So - trial and error I went - disabling, enabling, profiling, stepping through the code... nothing I removed or added made a blind bit of difference. It never occured to me (well actually obviously it did eventually) to look at the css style options I was using elsewhere on the page.
The problem I was getting was on this underwater scene. (It's not finished yet, the game is totally in progress). Whenever Chrome or Safari loaded this scene, they would go from 1 frame every 12 milliseconds to 1 every 25 in Safari and 1 every 80!! on Chrome. FireFox handled this page perfectly, not even flinching. The only thing that was different to many other scenes in the game, was that this one uses quite a full on blue background... but what made me completely ignore this fact was that I had other scenes with full graphic backgrounds that gave no problems for any of the browsers.
Eventually I spotted one difference that I hadn't considered. To save rendering time, and to get the browsers to use their routines rather than my s(lowly) javascript code, instead of painting the scene backgrounds in the canvas (clearing and then redrawing every frame) I am setting the background on a div that floats behind the canvas tag. With the canvas tag mainly being transparent it all works as expected. Now this I thought was quite an obvious thing to do. However, In order to render my background image to the right size for the underwater scene (compared to the other scenes) I was using "background-size" set to 100% 100%. The second I removed this styling, Chrome and Safari were back to flying along at a decent speed. It seems, for whatever reason, webkit doesn't cache the resized version of the image. So each time Chrome or Safari had to re-render the background image because my canvas tag had trashed it by drawing on top, it seems that they both had to resample/rescale the image again. Rather ridiculous really... as usual hats off to FireFox for doing what you'd expect.
Unfortunately despite working out what the problem is, I don't really have a nice solution. My only options are to fallback to the old method of stetched background images (an image tag with 100% dimensions) and see if that works differently. Or if that fails, use another canvas tag layered behind my first one and specifically paint the background to the right size. I could create a php script that would render the background image to the right size "on request" but that seems a little overkill for what is essentially a mood setting backdrop.
Yet another thing to be disappointed about in terms of Webkit. Don't get me wrong, I love the fact that Webkit is there for so many people / programs and devices to use. I was blown away slightly the first time i saw Flash Air with it's own built in browser... and I love using my Kindle 2 browsing around whereever I want... But I just keep coming across really obscure bugs and it's winding me up :)
- 2 comments • Category: Coding, Game Dev, JavaScript
- Share on Twitter, Facebook, Delicious, Digg, Reddit
Don't ask me why but I've just finished installing the latest recommend version of Drupal 7. I'd been hearing quite a bit of chatter about it recently (after the initial buzz at the beginning of the year (and after the constant comments on the dev channel the year before that)). So I decided that maybe now would be a good time to see what improvements had been made - In my opinion there was a lot needing to be done from Drupal 6...
Before getting started however I did a little bit of research to see what others were saying, and it seemed unanimous really:
- Drupal 7 is cleaner and more though-out than D6
- Scalability is better, but performance is slightly worse.
- There are a lot of modules that have been ported (D7 promise), but many useful ones are still at alpha/beta stages.
- Module Installation and dashboard are +1 by all
From my point of view it only took me about 30 minutes this morning to get a clean install working using SQLite with my "must have" modules installed (Views,CTools,Panels). Which is far better than my experiences before with D6. I quickly created some new Views (like the new interface for Views!), tied those in to new pages controlled by Panels (Panels is now even more extensive!) exposed via Blocks (Blocks are blocks). I got Drupal's basic search working (I haven't looked in to anything more complicated like FuzzySearch altho I am currently looking in to Google Custom Search). And I then customised the main menu to be as I wanted. So all in all, good, and needed minimal time to look things up. However, I always found this to be the case really with Drupal. It's very quick to put together the large, general bits and pieces of a site... Your time just gets eaten up by editing or fixing the more smaller and specific issues which take forever to find.
Anyway, I haven't had too much time to play around now. Nothing from the code point of view. But so far the admin/front-end is a lot cleaner but totally re-arranged and I will admit to getting a little/lot lost. At least there is the feeling that once I've learned the interface it will be clearer and quicker to navigate than D6. The most annoying thing for me with D6 is that nothing was where I'd expected it to be.. whether that's because non-techy people just have very strange thought processes ;) or D6 just was very strange in itself. So D7 is an improvement... I just expect things in D6 places and haven't found everything yet ;)
So overall... since my check in January it still seemed to me that for use on a large-scale projects things would probably ok as long as you have time for bespoke modules (or you have flexibility with how things need to work), for smaller and personal CMS projects it would definitely be my choice just because it seems far more thought out than anything else out there. The "install module from URL" feature is very nice, but quite why this didn't exist previously I have no idea... it's hardly a new concept or difficult to implement, especially when you have complete control over where and how your module developers upload their contributions. I don't mean to sound negative but much of what I have seen so far in D7 is just common sense, obviously achieving common sense on a large scale project is quite difficult if you don't start out with that premise. So I'd say the "hats off" achievement isn't so much the actual new features I've come across, it's getting them all ready and working in harmony across such an open network... which is what they've achieved.